ardelvo.

Explore the technology.

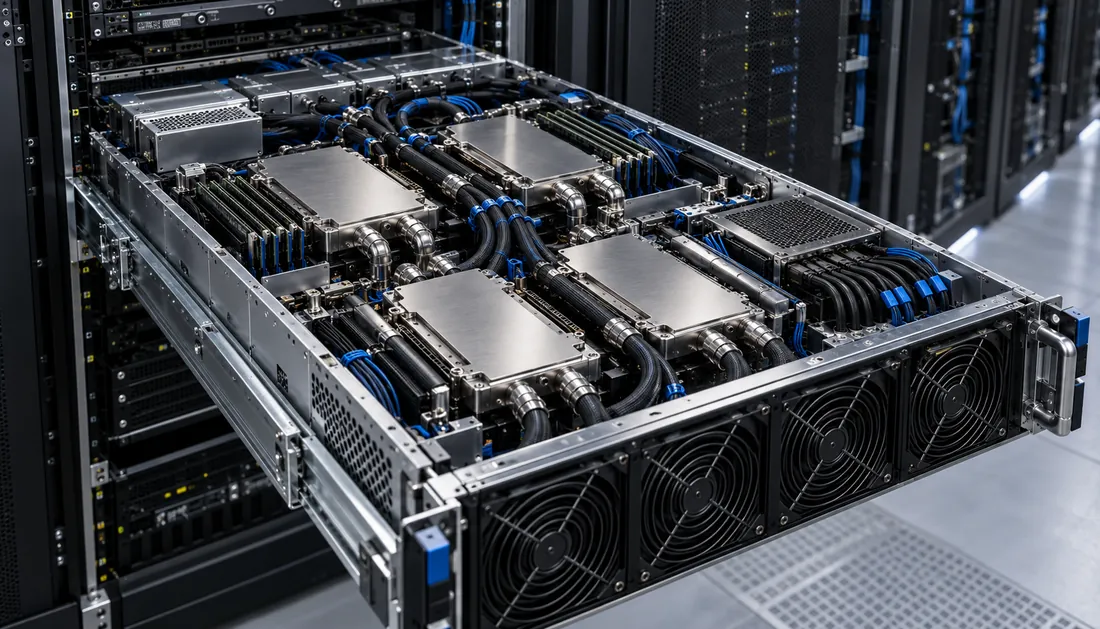
Explore accelerators, storage and memory, then follow the connections from a single server to a complete cluster.

Conceptual infrastructure illustration

Size your inference workload.

Estimate GPUs, memory, storage, power and budget with adjustable assumptions.

Open the calculator

Understand the components.

Go deeper into the components behind the architecture. Each guide includes product examples and links to manufacturer documentation.

Compare the platforms.

Selected manufacturer specifications. Product announcements do not establish local stock, delivery dates or Ardelvo reseller status.

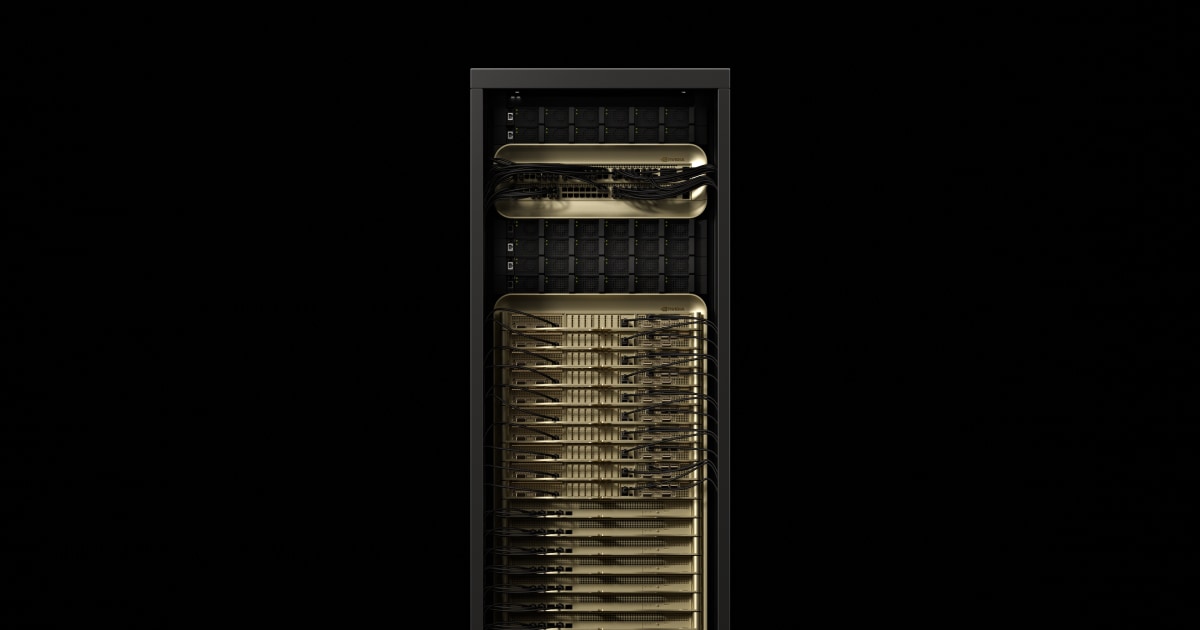
NVIDIA GB300 NVL72 rack system
GB300 NVL72 rack · Product image: NVIDIA

B300 & GB300 NVL72

B300 is the accelerator; DGX B300 is an eight-GPU server. GB300 NVL72 combines Blackwell Ultra GPUs and Grace CPUs across a liquid-cooled rack.

DGX B300
8 GPUs · 2.3 TB GPU memory
GB300 NVL72
72 GPUs · 36 Grace CPUs
Memory per GPU
288 GB HBM3e

Planning implication A server and an NVL72 rack require different power, cooling and service arrangements. Specify the complete system, not just the GPU name.

NVIDIA DGX specifications GB300 rack design
AMD Instinct MI350 series accelerator module
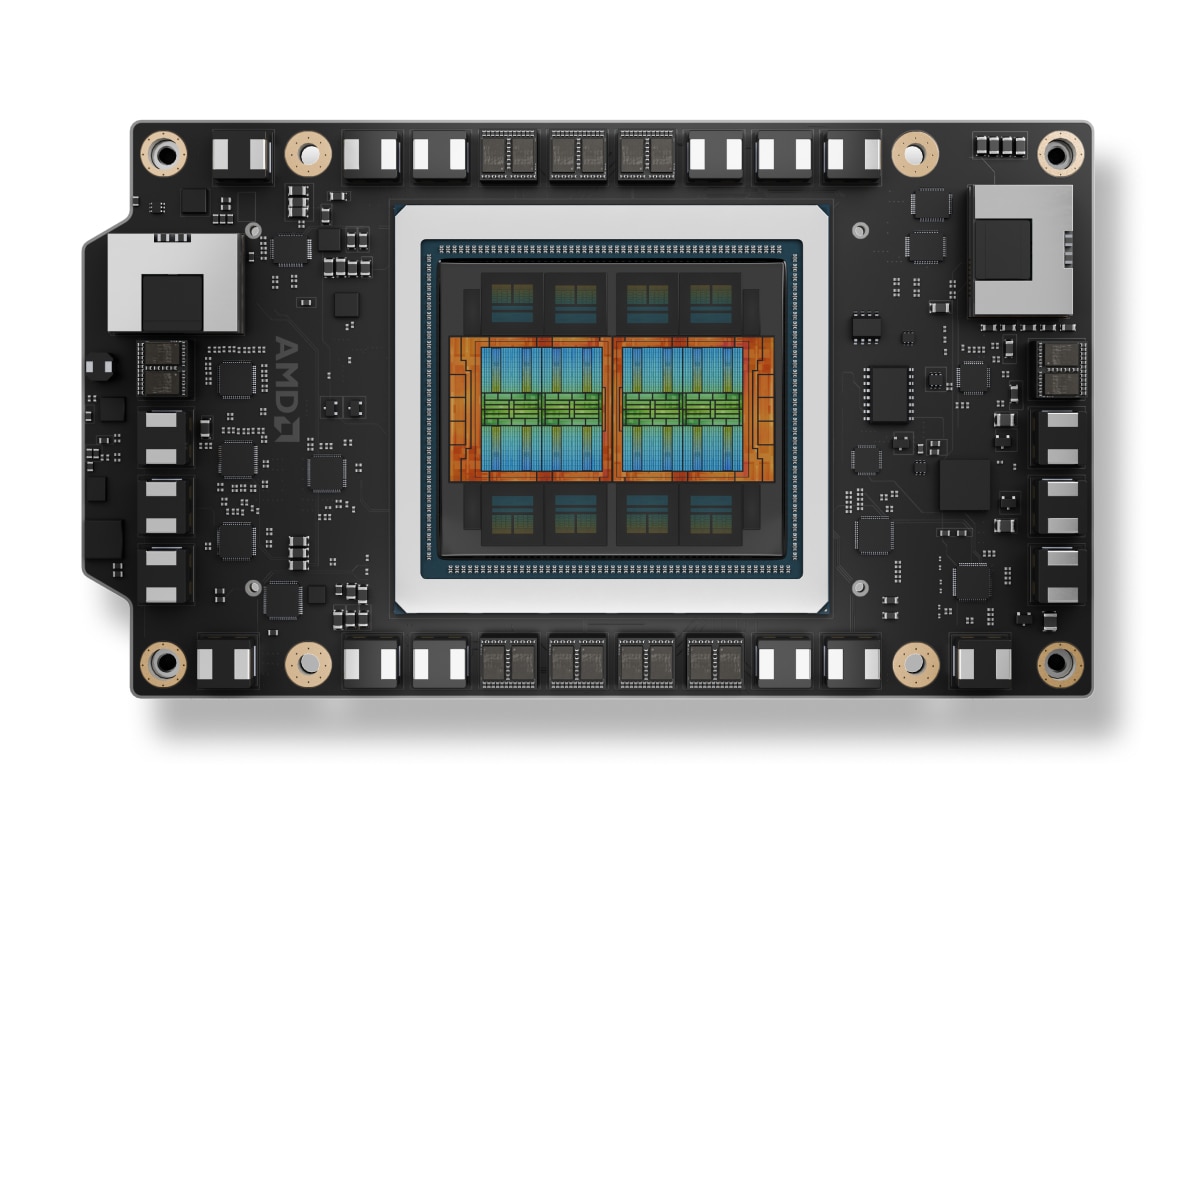
MI350 series product image · AMD

Instinct MI355X

A high-memory accelerator for AI and HPC, with support for microscaling data types. Evaluate the ROCm software path alongside the hardware configuration.

Architecture
AMD CDNA 4
GPU memory
288 GB HBM3E
Memory bandwidth
8 TB/s

Planning implication Validate your framework, kernels and model-serving stack on the intended software release before committing to a platform.

AMD product specifications

From GPU servers
to integrated racks.

New designs bring the CPU, accelerator, networking and cooling closer together. Procurement and facility planning increasingly need to happen at the same time.

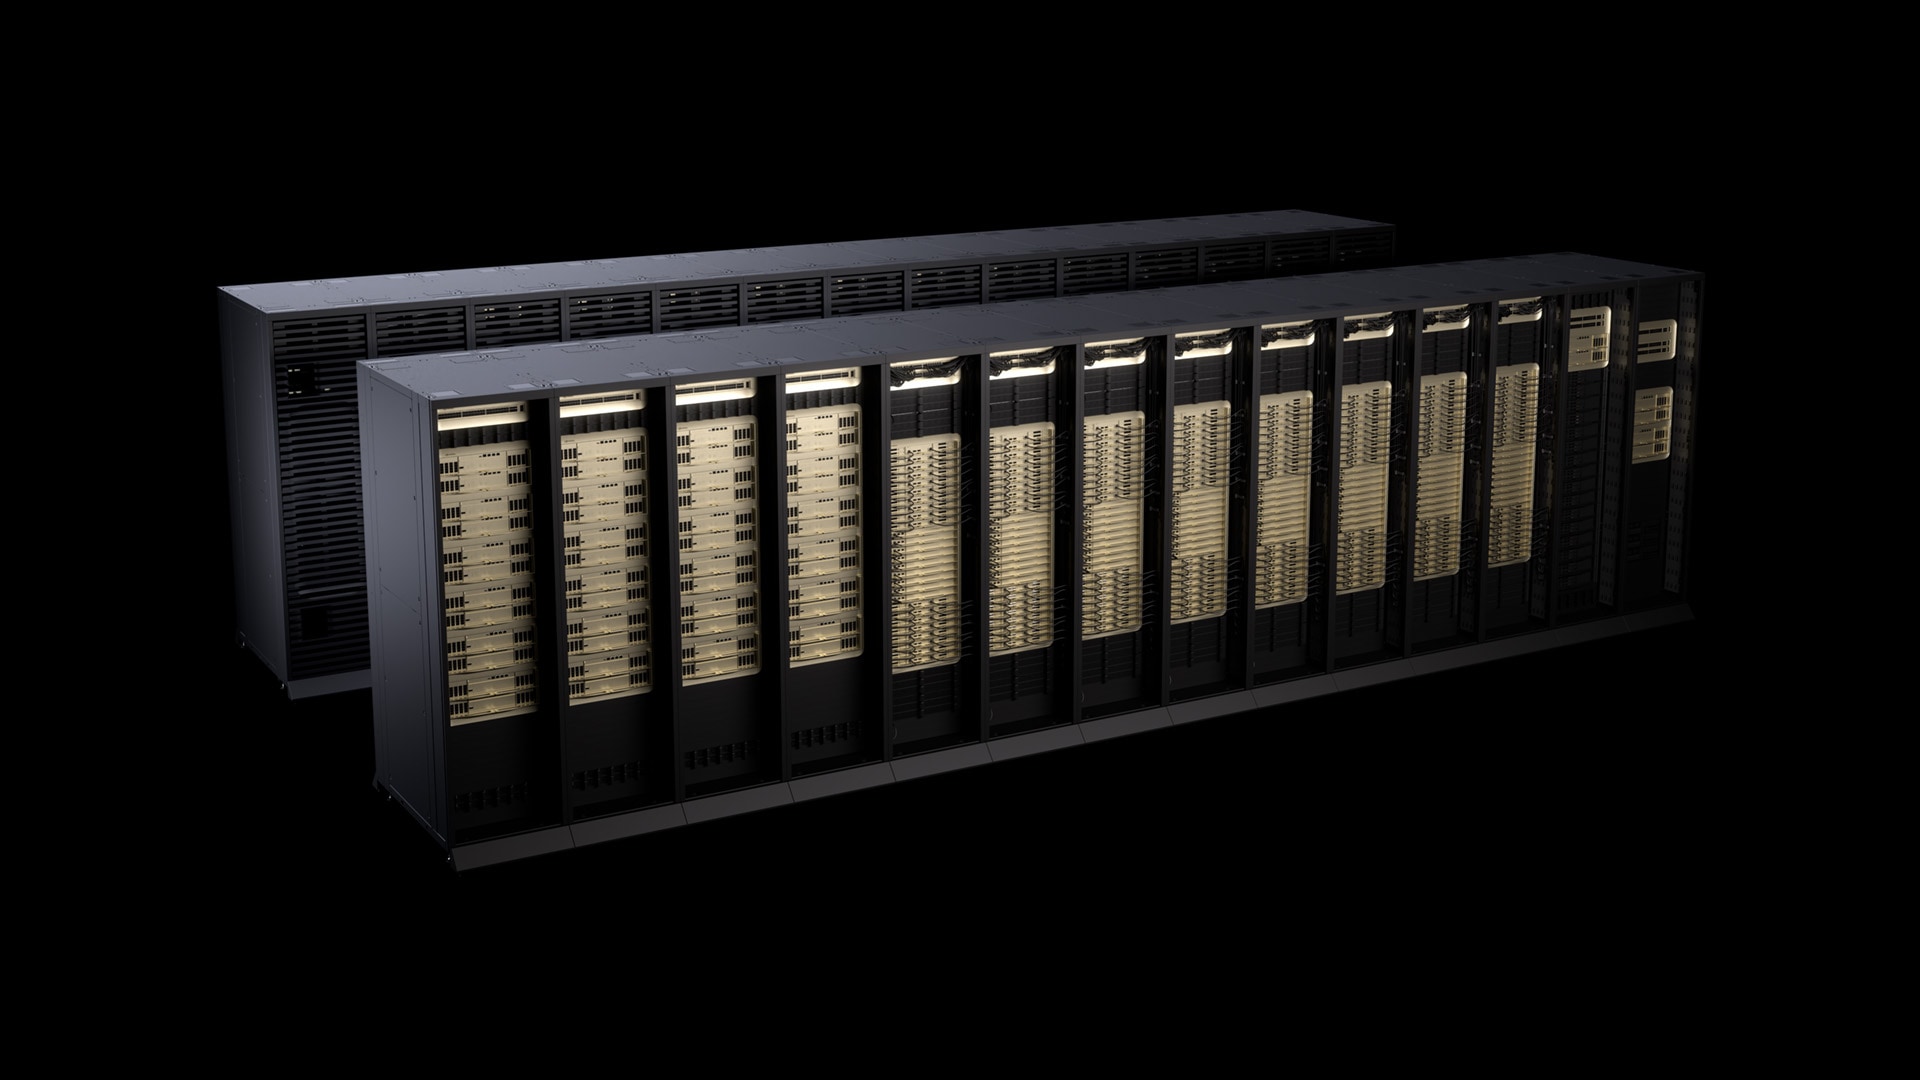
NVIDIA DGX Vera Rubin NVL72 rack system product rendering
DGX Vera Rubin NVL72 · Product image: NVIDIA
NVIDIA

Vera Rubin NVL72

Rubin moves to HBM4 memory, paired with Vera CPUs in an NVL72 platform. NVIDIA’s published configuration lists 288 GB HBM4 per GPU. Review the current system specification and OEM delivery plan before sizing a deployment.

Explore NVIDIA’s Rubin platform
AMD

Instinct MI455X / Helios

AMD’s announced Helios design combines 72 MI455X GPUs with 18 sixth-generation EPYC CPUs and Pensando networking. It is a rack-scale platform to evaluate with the supplier’s rollout and qualification schedule.

Read AMD’s 2026 platform announcement

Follow the system.

These simplified logical diagrams explain system relationships. They are planning illustrations, not vendor wiring diagrams or construction designs.

LOGICAL VIEW / ONE SERVER
Applications & model runtimeFramework · inference engine · scheduler
↕
Host CPUsSystem memory
↔
GPU groupAccelerators + HBM
↕
Local NVMeCache & checkpoints
Network adapterData & cluster traffic

Start at the node.

The model, precision and context length affect memory demand. GPU-to-GPU links affect how efficiently work can be divided inside a server.

  • Check usable GPU memory against the complete workload.
  • Confirm CPU, memory and local storage requirements.
  • Validate the exact GPU topology and software stack.

HBM is high-bandwidth memory attached to the accelerator. Aggregate capacity does not automatically behave like one shared memory pool.

Further reading: NVIDIA NVL72 reference architecture · DGX B300 system guide

What belongs
on the shortlist?

Compare systems against a representative workload. Peak FLOPS alone cannot tell you what a production deployment will deliver.

01

Memory

Account for model weights, activations, KV cache and runtime overhead. Training and inference can have very different requirements.

02

Software

Check supported frameworks, drivers, kernels and serving tools. Run your model on the intended software versions.

03

Communication

Separate GPU memory bandwidth, in-system interconnect and network bandwidth. Each addresses a different bottleneck.

04

Operations

Include facility changes, installation, spares, support and energy in the evaluation—not only the equipment price.

Bring the shortlist.
We’ll work through the infrastructure.

Share the workload, preferred platforms and site constraints.

Discuss your project